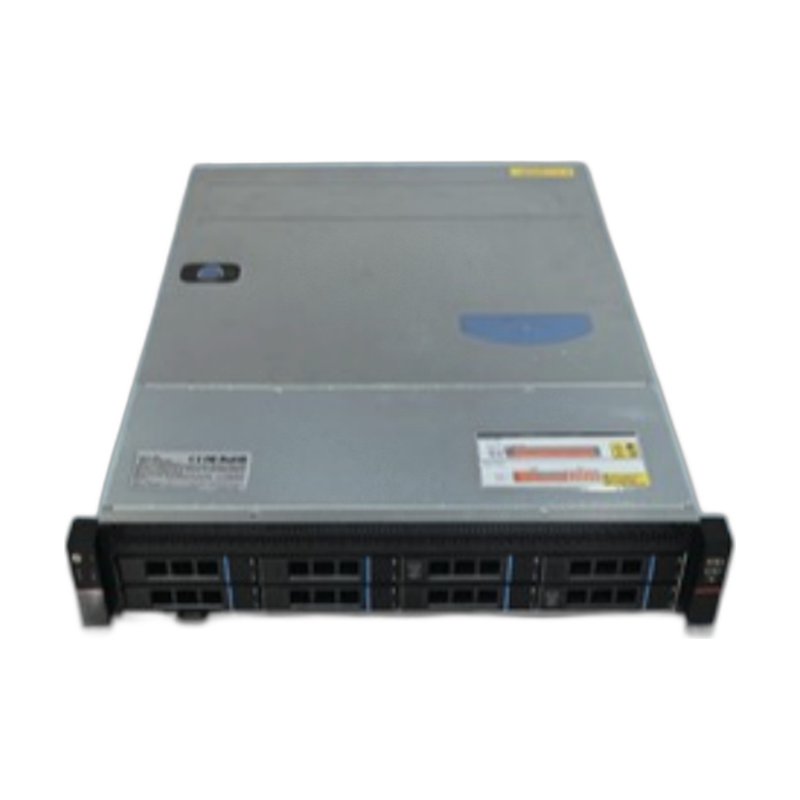
A 2U rack-mount AI server that combines several SOPHGO AI processors in one chassis for up to 576 TOPS INT8 per unit. It runs private LLMs such as DeepSeek, Qwen and QwQ-32B, model training and tuning, and large-scale video analytics in your own data room.
Overview
When one edge box is not enough, the 2U AI Training & Inference Server brings data-centre-class AI compute into a standard 19-inch rack. Multiple SOPHGO AI processors, with 7.2–64 TOPS INT8 per chip, add up to as much as 576 TOPS INT8 per unit, and the 8-core Arm A53 / RISC-V host processors manage scheduling, storage and networking.
The server is designed for organisations that want to keep models and data on their own premises. It hosts open-source large language models such as DeepSeek, QwQ-32B and Qwen2.5 alongside private models. With TouchVision’s AI Model Training & Inference Platform it covers the full workflow from dataset preparation to deployment. Hardware H.264/H.265 codecs let the same unit run video structuring for large camera estates, and Docker, Python, OpenCV and FFmpeg make integration with existing systems straightforward.
Key features
- SOPHGO AI computing platform with 8-core Arm A53 / RISC-V host processors
- Up to 576 TOPS INT8 per unit (7.2–64 TOPS INT8 per chip)
- Hosts open-source LLMs (DeepSeek, QwQ-32B, Qwen2.5) and private models
- Model training, tuning, quantization, export and inference with the TouchVision AI platform
- H.264/H.265 hardware encoding and decoding for multi-channel video analytics
- TensorFlow, Caffe, MXNet, PyTorch, ONNX and PaddlePaddle support
- Docker deployment, Python development, OpenCV and FFmpeg acceleration
- Standard 19-inch 2U rack chassis with front-accessible drive bays
Specifications
| Item | Specification |
|---|---|
| Form Factor | 19-inch 2U rack-mount |
| AI Platform | SOPHGO AI processors |
| AI Performance | Up to 576 TOPS INT8 per unit |
| Host Processors | 8-core Arm A53 / RISC-V |
| Video | H.264/H.265 real-time HD encoding and decoding |
| Large Models | DeepSeek, QwQ-32B, Qwen2.5; private models |
| Frameworks | TensorFlow, Caffe, MXNet, PyTorch, ONNX, PaddlePaddle |
| Software | Docker, Python, OpenCV, FFmpeg |
| Power Efficiency | < 1 W per TOPS (INT8) |
Specifications are based on manufacturer data and may change. Ask for the latest datasheet for your configuration.
Applications
- Private enterprise LLM and knowledge-base hosting
- Central AI video analytics for parks, campuses and cities
- Model training and fine-tuning for industrial defect detection
- Smart construction, chemical plant, power grid and gas station projects
- Organisations with data-sovereignty requirements
Related industry solutions: AI Video Analytics & Smart Safety · Industrial Automation & Machine Builders · Energy & Power Automation
Customization and ordering
The 2U AI server can be customized for OEM projects, and small-batch pilot orders are supported. Request a quote or sample, chat on WhatsApp (+86 135 0532 6001), or read about our OEM/ODM service.
More in this category: On-Premise LLM & AI Agent Appliances · Related: Edge AI Computers & Video Analytics Boxes
Frequently asked questions
How much AI compute does the 2U server provide?
Up to 576 TOPS INT8 per unit, from multiple SOPHGO AI processors in one 2U chassis.
Can it train models as well as run inference?
Yes. With TouchVision’s AI Model Training & Inference Platform it covers dataset preparation, training, validation, quantization, export and inference deployment.
Which large language models are supported?
Open-source models such as DeepSeek, QwQ-32B and Qwen2.5 run locally, and private models can be hosted as well.
When should I choose the 2U server instead of an edge box?
Choose the 2U server when you need to centralise many camera streams, host larger LLMs for many users or train models on-site. Edge boxes such as the YZ-B011 suit single sites with up to 16 analytics streams.