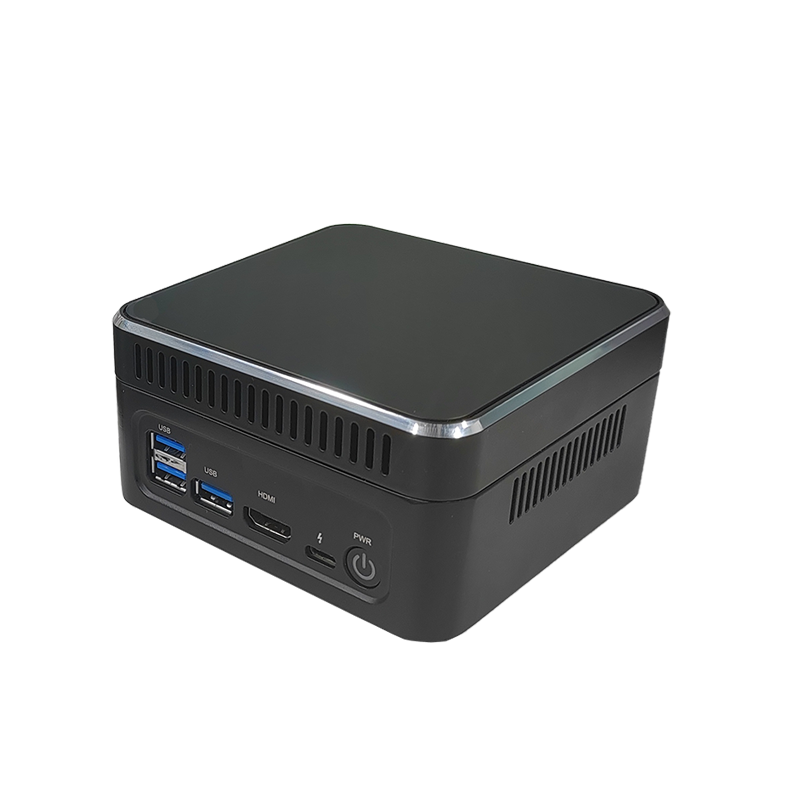
A 17 W edge appliance (BM1684X, 32 TOPS INT8) that runs DeepSeek and Qwen models and a private knowledge base fully on-premises, and can also analyse 32 video streams.
Overview
The YZ-B033 brings large language models to the edge without a GPU server or cloud subscription. The BM1684X accelerator delivers 32 TOPS INT8 with FP32/FP16/BF16/INT8 mixed precision and is pre-adapted for DeepSeek and Qwen model families. Out of the box it supports knowledge-base Q&A over PDF, TXT, DOCX, PPTX and image files, text-to-image generation, image and video search by text, speech-to-text, text-to-speech and code generation, all processed locally. It can also run 32-channel HD video analytics, so one device can serve both AI assistants and vision workloads.
Key features
- SOPHGO BM1684X; 32 TOPS INT8; FP32/FP16/BF16/INT8 mixed precision
- Pre-adapted for DeepSeek and Qwen open-source LLMs
- Private knowledge base Q&A (PDF, TXT, DOCX, PPTX, images)
- Text-to-image, image/video search by text, ASR, TTS, code generation
- 32-channel HD video analytics; 32× 1080p@25 decode, 12× 1080p@25 encode
- Typical power 17 W; -20 to +70 °C
- Dual LAN, TF, debug port
Specifications
| Item | Specification |
|---|---|
| AI SoC | SOPHGO BM1684X |
| AI Performance | 32 TOPS INT8; FP32/FP16/BF16/INT8 |
| Models | DeepSeek, Qwen (others on request) |
| Video | 32× 1080p@25 decode; 12× 1080p@25 encode; 32-ch analytics |
| Memory / Storage | On request |
| Interfaces | 2× LAN, TF, debug (full list on request) |
| Power Consumption | 17 W typical |
| Operating Temperature | -20 to +70 °C |
Specifications are based on manufacturer data and may change. Items marked “on request” are configured per project; ask for the latest datasheet.
Applications
- Private enterprise knowledge assistants
- Factory and field-service document Q&A
- Edge offices with data-sovereignty requirements
- Combined AI vision + LLM sites
Related industry solutions: AI Video Analytics & Smart Safety · Industrial Automation & Machine Builders
Customization and ordering
The YZ-B033 can be customized for OEM projects: interfaces, enclosure or mounting, firmware/OS image and branding. Small-batch pilot orders are supported. Request a quote or sample, chat on WhatsApp (+86 135 0532 6001), or read about our OEM/ODM service.
More in this category: On-Premise LLM & AI Agent Appliances
Frequently asked questions
Which LLMs run on the YZ-B033?
It is pre-adapted for DeepSeek and Qwen model families; other open-source models can be evaluated on request.
Does data leave the device?
No. Inference, knowledge-base indexing and speech processing run locally, so documents and prompts stay on-premises.
How much power does it draw?
Typical power consumption is 17 W.